
Agentic AI vs. Generative AI: What’s the Difference?
Drafting a customer reply and resolving the case are different jobs. The right approach depends on what you want the system to do.
Patrick Chemoul, CEO of Dopweb
Updated November 5, 2026
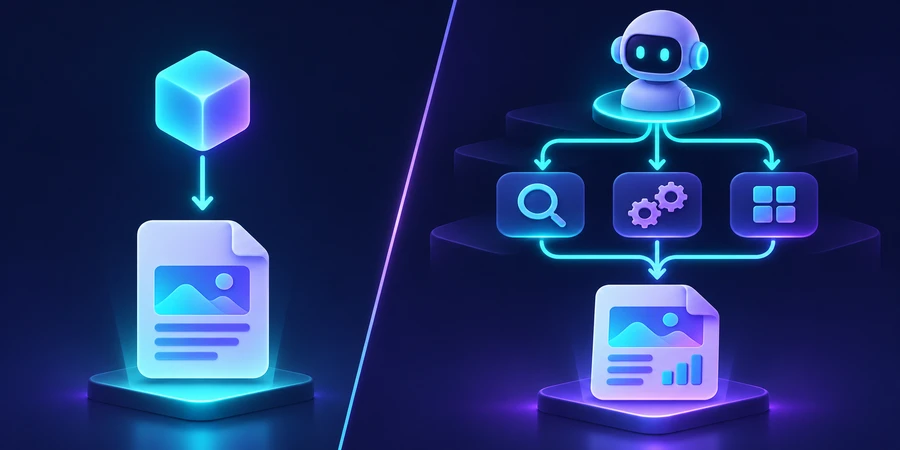
Generative AI produces or transforms content. Agentic AI can use a model and connected tools to pursue an outcome over several steps. Both can operate in the same application, so compare the work each approach is responsible for.
Agentic AI vs. generative AI on the same customer request
A prospect emails to ask whether a quote is still valid and whether it can be revised. A generative model can identify both questions, summarize the request, and draft a reply. The sales rep may still need to locate the latest quote, verify the terms, and check who owns the account. The drafting step can still pay off because it is easy to review and does not require write access to the CRM.
A rules-based workflow can look up a quote using a valid ID, calculate its expiration date, and flag its status. An agent may help if the system needs to decide how to find the right document, compare competing versions, or ask for clarification. The key question is which decisions need context and which can be resolved through a stable rule. The agentic AI guide walks through the same distinction for a support case. IBM explains the distinction between content generation and goal-directed action in its comparison of agentic and generative AI.
Separate interpretation from authorization
A model can infer that the prospect wants to remove a line item. The application still needs to verify which user is allowed to change the quote and confirm the correct record. Show the original and proposed terms to the reviewer. Store the approved version and tie the approval to that specific change, so a second revision cannot reuse the first approval.
How to design a hybrid workflow
Illustrative scenario, not measured results 80 rules-based requests 20 exceptions out of 100 2 paths to compare
Put reproducible decisions in rules
List the decisions two qualified team members would make the same way given the same inputs. A unique quote ID, a recorded sent date, and a fixed validity period are enough for a deterministic expiration check. Keep those checks, record validation, and deduplication in the workflow automation layer. When a policy changes, your team can update the rule and rerun the cases that depend on it.
Use generative AI where language varies
Ask the model to extract the questions, separate facts from assumptions, and draft a response from the approved terms. Send only the relevant quote and notes. If the model has insufficient evidence, the output should say which field or source is missing. Review for factual errors and unintended promises as well as tone. A polished email is of little value if the rep has to verify every detail from scratch.
Let an agent choose among a few authorized tools
Some inquiries require one lookup. Others require a search in the CRM, a check of two documents, and a follow-up question. In that situation, the agent can choose which lookup comes next. Give it dedicated access to the relevant records and verify the tool arguments in the application. Set a maximum number of attempts and an explicit handoff when it cannot identify the right customer or quote.
Measure where additional research pays off
Some quote questions can be answered from the quote itself. Others refer to terms in a separate agreement. A drafting model given only the quote might produce a reply that misses a material detail. An agent can look up the agreement when the request calls for it and the account permits access. If the document is unavailable, the draft should explain what a rep needs to verify.
Score those cases as a separate group. Compare a version that receives only the quote with one that can choose an additional lookup. Record how often the extra step improves the answer and how much review it adds. If the agent reads several records for routine inquiries, include that work in the comparison.
Revisit decisions that become predictable
A common exception may turn into a stable rule after your team understands it. Move that check into the workflow and keep the model for language tasks or unresolved cases. Rerun the known exceptions after the change. This gives your team a way to simplify the process while retaining the improvement that justified the pilot.
Run a side-by-side evaluation
Start with examples that reflect the mix of work your team actually sees. Include missing IDs, duplicate accounts, expired quotes, and documents revised after the first send. Record the correct quote version, acceptable reply, and prohibited actions for each case. Hold back some examples until the end to see whether an improvement carries over to cases your team did not tune against.
Run the rules-based version, the drafting version, and the agent on the same inputs. For rules, record how often the case needs a manual path. For drafting, measure the quality of the reply and the research still required. For the agent, measure whether the selected sources are correct, whether the system escalates at the right time, and how much the extra tool calls cost. Use the same scoring guide and review team for all three.
Example evaluation or acceptance criteria 30 cases per approach 5 ambiguous cases included 1 shared scoring guide
Illustrative cost comparison
Suppose the drafting approach costs $48 in model usage and review time for a test batch, and 24 of 30 cases are handled correctly. That is $2 per correct case. If the agent costs $72 and handles 27 correctly, the cost is about $2.67 per correct case. The extra $24 bought three additional correct outcomes in this example. Check whether those outcomes are valuable enough to justify the operating difference and whether the additional accuracy holds up on the cases that matter most.
Score drafting and research separately
Ask reviewers to distinguish wording edits from missing evidence. A drafting model may save writing time while the agent saves lookup time. Tracking both helps you see which improvement is worth keeping.
How Dopweb can help you choose
We can take one business process, build a narrow comparison, and help your team define what a correct outcome looks like. For quote follow-up, that could mean a standard workflow for clear requests, a drafting step for replies, and an agent that researches a limited set of exceptions. We measure the handoffs and review time with you so the selection reflects actual work.
If an agent earns a place in the process, Dopweb can integrate the tools, limit access and model context, and document which decisions are owned by staff. Your team retains control of its accounts and has a test set it can rerun when the process changes. Explore Dopweb’s AI agents and workflow automation service.
For a broader lead journey, see how to implement marketing automation before adding agentic behavior. A clear intake, owner, and exit condition make it easier to isolate the exceptions that merit a pilot.
Related guides on agentic AI
About the author — Patrick Chemoul, CEO of Dopweb
Patrick Chemoul leads Dopweb, an agency helping businesses with websites, software, and automation. The agency also provides AI agent integration and team training. Learn about Dopweb.
Frequently Asked Questions
Does agentic AI replace generative AI?
They can work together. An agent can use a generative model to draft a reply inside a larger process.
Is every chatbot an agent?
Some chatbots answer questions. Others can use tools and act within an assigned scope.
Can I use both rules and AI?
Yes. Rules can handle routine steps, while a model helps interpret an exception.
How should I compare them?
Test the same cases and compare correctness, review effort, and total cost.
Let’s Talk About Your Workflow
Tell us what your team wants the agent to handle. We’ll discuss the scope, integrations, and controls needed for a first pilot.